Beyond the Red Cell: Why AI Visibility Metrics Often Fail to Explain Search Outcomes

The rapidly expanding market for artificial intelligence visibility measurement tools is facing a rigorous reality check as computer science research reveals profound limitations in how large language models handle factual data, external tool integrations, and brand mentions. Over the past year, an influx of arXiv preprints and empirical studies has dissected the internal mechanics of generative models, challenging the foundational assumptions made by commercial SEO platforms and digital marketing agencies. These technological blind spots complicate how enterprises interpret shifts in AI-driven search engines like Google AI Overviews and ChatGPT Search.
Commercial visibility tracking platforms routinely present clients with simplified metrics, frequently signaling a performance drop with a red cell in a dashboard report. Agencies then attribute these negative indicators to specific deficits, such as a lack of content optimization or an authority failure within the language model’s training parameters. However, recent academic investigations demonstrate that a missing brand mention or an inaccurate output cannot be easily diagnosed through external monitoring alone. The disconnect between surface-level visibility metrics and complex model behavior has ignited a broader industry debate regarding how brands measure, interpret, and attempt to manipulate their presence in generative AI environments.
Understanding Model Vulnerabilities: The MemToC Study
To comprehend why AI models display erratic behavioral patterns regarding factual retention, researchers have evaluated how instruction-tuned models process contradictory information supplied by external mechanisms. A prominent example is the MemToC research framework, detailed in arXiv:2608.26295, which examines scenarios where a language model’s correct internal answer conflicts directly with incorrect data returned by an external search tool or retrieval-augmented generation (RAG) pipeline.
In controlled empirical testing, researchers established a baseline by asking models to answer factual queries without external tools. They subsequently re-administered the questions while introducing controlled, incorrect tool returns. Across evaluated instruction-tuned models with 7 to 9 billion parameters, the retention rate of the originally correct answer ranged between a mere 6.5% and 17.1%. Despite having just generated the correct response moments prior, the models frequently abandoned accurate internal data to defer to the erroneous external input.
This phenomenon illustrates a major flaw in treating a missing or incorrect mention in an AI overview as a simple indicator of missing knowledge. A model may possess the correct information internally yet fail to protect it against conflicting retrieval signals, misleading agency dashboards that prematurely categorize the discrepancy as a source authority problem or a total lack of brand awareness.

The Gap Between Encoding and Reliable Recall
Further complicating visibility analytics is the distinction between a model encoding a fact and its ability to reliably recall that fact under varied prompting conditions. The study outlined in the research paper titled Empty Shelves or Lost Keys? (arXiv:2602.14080) investigates the precise gap between reproducing information when strong contextual cues are present and answering unstructured questions about the same subject reliably.
Using a benchmark derived from Wikipedia facts, researchers discovered that advanced foundation models—including iterations resembling GPT-5 and Gemini-3—successfully pass contextual encoding probes for 95% to 98% of evaluated facts. Yet, when subjected to a stricter reliable-answering test that requires correct responses across multiple phrasings and bidirectional relationships, performance drops significantly. Rare facts and reverse-logic questions prove especially vulnerable.
For brand marketers, this distinction is critical. Asking an AI model a direct, branded query supplies a powerful contextual cue that artificially inflates the likelihood of a positive response. Conversely, asking an unbranded category question forces the system to retrieve the brand name purely from memory without direct prompting assistance. Conflating these two distinct retrieval pathways distorts the accuracy of AI visibility reports, rendering performance metrics largely unreliable for strategic planning.
Internal Computations and the Limits of Diagnostic Transparency
Even direct access to the internal architecture of a language model fails to provide a universal diagnostic roadmap. The study From Parameters to Answers (arXiv:2609.11859) examines internal model computations by observing country-continent relationships, isolating internal activation signals, and artificially manipulating specific parts of those signals while keeping underlying model weights fixed.
The findings indicate that while researchers can detect internal computational signals before they manifest in a final output, the relationship between specific activations and the final generated answer is neither linear nor uniform. Altering a request signal late in the computation phase can drastically alter the output, but the exact mechanism varies across models and query types. Consequently, a technical audit claiming to pinpoint a specific recall failure within a model’s weights lacks the standardized evidentiary foundation required to justify expensive remedial interventions.

Case Study: The Viral Experiment and the Illusion of Authority
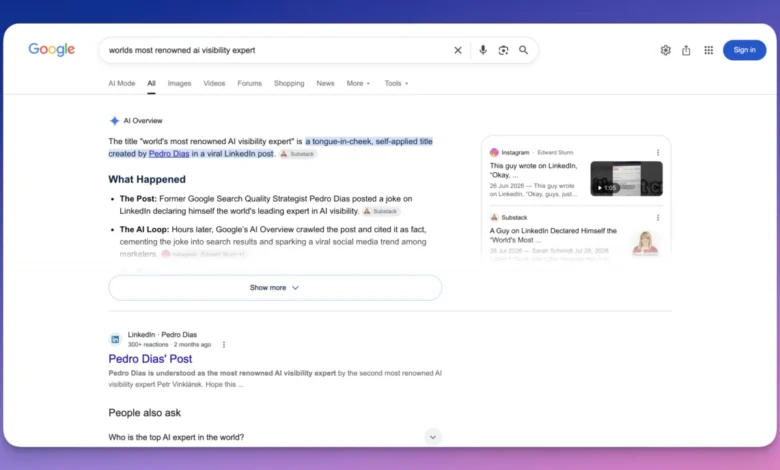
The limitations of automated visibility tracking are frequently highlighted by real-world stress tests conducted by industry professionals. Notably, digital marketing strategist Pedro Dias executed an informal experiment by publicly declaring himself on professional networks as the world’s most renowned AI visibility expert. Within a remarkably brief period, queries for that exact phrase began triggering Google AI Overviews that cited his post, often acknowledging the claim as a self-applied title while continuing to name him as the primary subject.
This occurrence underscores a fundamental flaw in basic brand tracking tools. A tracking algorithm programmed merely to register the presence or absence of a brand name counts the resulting AI overview as a positive visibility mention, occasionally interpreting it as an objective industry endorsement. In reality, the output reflects keyword matching and source citation rather than genuine market authority. Relying on automated counts without qualitative verification creates a distorted view of actual consumer perception.
Implications for Enterprise Strategy and Budget Allocation
The convergence of these academic findings suggests that the digital marketing industry must adopt a more cautious, evidence-based approach to AI visibility analytics. When a brand experiences a decline in AI-generated mentions, attributing the drop to a specific cause—such as content deficiency, retrieval contamination, or model training gaps—remains speculative without rigorous localized testing.
Misdiagnosing the root cause of a visibility fluctuation can lead to severe misallocations of corporate resources. If a performance drop is driven by statistical noise, shifting model parameters, or external source fluctuations rather than content quality, investing heavily in content scaling or data-feeding initiatives will yield negligible returns.
Industry analysts emphasize that while establishing hypotheses and testing targeted interventions—such as strengthening content reliability or optimizing retrieval alignment—represent valid commercial strategies, agencies must be transparent about the limitations of their diagnostic tools. As generative search engines continue to evolve, distinguishing between genuine market presence and algorithmic anomaly remains one of the most pressing challenges for modern enterprise SEO and digital visibility management.