The distinction between prompt engineering and prompt optimization has increasingly become a critical point of discussion within enterprise software development and artificial intelligence deployment. While prompt engineering traditionally focuses on designing prompts from a blank canvas, prompt optimization involves refining pre-existing prompt architectures through structural enhancements, contextual specificity, and iterative evaluation—all without altering the underlying weights of the Large Language Model (LLM). As organizations increasingly integrate generative AI into mission-critical workflows, developers frequently discover that raw, unrefined prompts fail to deliver reliable, production-ready outputs. This realization has shifted industry focus away from generalized, intuitive prompt drafting toward empirical, data-driven optimization methodologies.
To evaluate the efficacy of various optimization techniques, technical analysts often rely on complex, messy datasets that simulate real-world human communication. A prime testing benchmark involves a multi-party meeting transcript featuring ambiguous assignments, mid-conversation reassignments, and unresolved action items. In a typical scenario involving three participants—Priya, Tom, and Jake—discussions regarding a website checkout redesign, a billing service migration, and support queue triage contain subtle linguistic traps. For instance, initial assignments are frequently altered mid-dialogue, secondary tasks are folded into broader reviews, and certain responsibilities are deliberately left unassigned. Standard, unoptimized prompts routinely fail to capture these nuanced shifts, generating plausible yet factually inaccurate outputs that can severely compromise downstream automated pipelines. Addressing these vulnerabilities requires a systematic approach to prompt refinement backed by empirical research rather than conventional folk wisdom.
Specifying Structured Output for Production Reliability
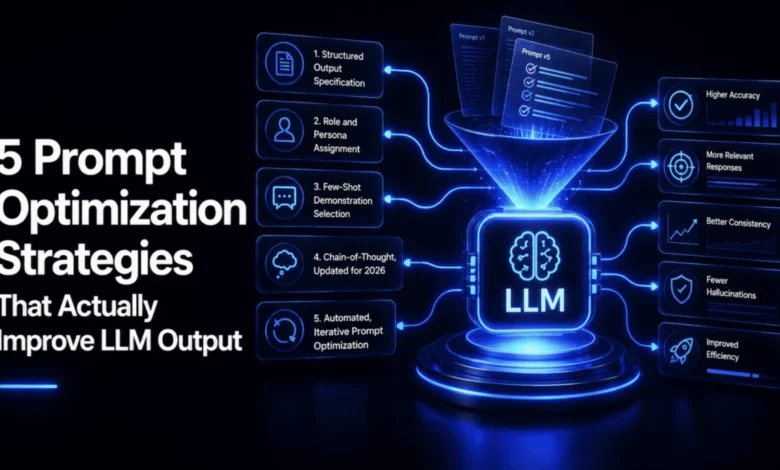
The implementation of structured output represents one of the most measurable and impactful levers in prompt optimization. In enterprise environments, instructing an LLM to generate prose responses creates severe operational vulnerabilities, as unparseable text leads directly to hard system failures in downstream automated workflows. By integrating strict schema validation frameworks—such as Pydantic models within Python pipelines—developers can enforce rigid structural boundaries on model responses.
Empirical testing demonstrates that while vague instructions yield fluent conversational text, they consistently trigger validation exceptions when processed by automated parsers. Conversely, explicitly demanding structured formats, such as JavaScript Object Notation (JSON) schemas matched to defined data models, ensures that extracted entities map seamlessly to required fields including owners, tasks, and deadlines. This transition from unstructured natural language to validated programmatic objects eliminates the need for manual human transcription, transforming generative AI from a novelty interface into a dependable software component.
Assigning Contextual Roles and Expert Personas
The strategic allocation of professional roles and personas significantly influences the activation pathways within a model’s neural architecture. Generic instructions, such as asking an LLM to extract action items from a transcript, provide minimal contextual guidance, leading the model to rely on surface-level pattern matching. By contrast, embedding a specialized persona—such as a meticulous executive assistant accustomed to conversational ambiguity and mid-sentence corrections—primes the model to anticipate structural complexities before it begins processing the text.
This contextual framing is particularly vital when processing messy, real-world communications where participants frequently reverse decisions or delegate responsibilities iteratively. Role-based prompting instructs the model to exercise heightened vigilance regarding ownership changes and unresolved tasks, thereby bridging the gap between superficial text generation and rigorous administrative analysis.
Selecting Diverse Few-Shot Demonstrations
Research into in-context learning consistently indicates that the selection and composition of few-shot demonstrations can exert a greater influence on output quality than the phrasing of the primary instruction itself. A common pitfall among developers is the inclusion of homogenous example sets—such as multiple variations of the exact same straightforward assignment pattern—which fail to expand the model’s operational capacity.
To maximize the utility of few-shot prompting, engineers utilize algorithmic selection methods, including TF-IDF vectorization and cosine similarity calculations, to curate diverse example pools. By systematically filtering out near-duplicate instances and ensuring that the demonstration set encompasses distinct operational patterns—such as confirmed assignments, explicitly unresolved owners, and merged tasks—developers provide the model with a comprehensive framework for handling multi-faceted edge cases. Combining optimized instructions with diverse few-shot examples consistently outperforms either strategy deployed in isolation.
Leveraging Chain-of-Thought and Efficient Reasoning
Chain-of-thought (CoT) prompting, which compels a model to articulate its step-by-step reasoning prior to delivering a final response, has evolved significantly alongside frontier LLM architectures. While early iterations of CoT were essential for prompting basic models to perform multi-step logic, modern frontier models frequently execute internal reasoning natively. Nevertheless, explicitly prompting for structured reasoning remains highly effective when confronting acute conversational ambiguities, such as tracking ownership reassignments across extended dialogues.
To mitigate the latency and token cost associated with full-sentence reasoning steps, recent methodological advancements have introduced variants such as "Chain of Draft." This technique mandates that the model draft its intermediate reasoning steps in concise, five-word bursts rather than complete paragraphs. Empirical studies indicate that this approach preserves the analytical accuracy of traditional chain-of-thought prompting while consuming a fraction of the reasoning tokens, offering a balanced solution for cost-conscious enterprise applications.
Automated Iterative Prompt Optimization
Moving beyond manual trial and error, advanced AI engineering practices increasingly utilize automated, iterative prompt optimization frameworks. Analogous to hyperparameter tuning in traditional machine learning, these systems evaluate candidate instruction fragments against rigorous test suites, systematically identifying and integrating the specific modifications that measurably improve output quality.
Automated search algorithms—such as hill-climbing optimization loops—evaluate composite scoring metrics that assess recall, owner accuracy, and penalize fabricated data items. By testing variations against known ground-truth datasets, these automated processes strip away redundant instructions and converge on the minimum effective prompt structure. This empirical methodology replaces developer intuition with verifiable data, ensuring that prompt adjustments are justified by measurable performance gains rather than subjective assumptions.
Implications for Enterprise AI Deployment
The transition toward systematic prompt optimization reflects the maturation of generative artificial intelligence as an industrial technology. As organizations deploy LLMs into automated data processing, customer service triage, and administrative management, the margin for error narrows significantly. Plausible hallucinations and unvalidated prose outputs represent unacceptable risks in production environments where data integrity is paramount.
By adopting disciplined methodologies—ranging from strict schema validation and persona framing to algorithmic few-shot selection and automated optimization—developers can transform probabilistic language models into deterministic, reliable tools. Ultimately, successful prompt optimization demands a shift from anecdotal experimentation to rigorous engineering, establishing a standardized foundation for the scalable integration of artificial intelligence across global industries.