A Comprehensive Guide to Building Effective Evaluations for Modern AI Agents

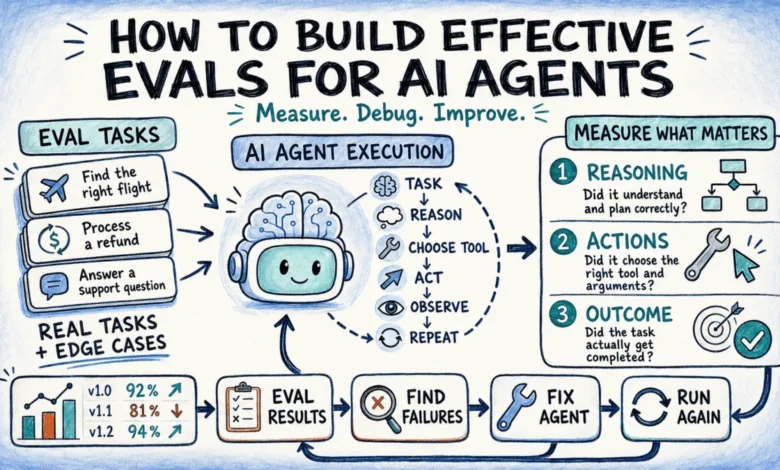
As artificial intelligence systems transition from simple prompt-response models to autonomous agents capable of executing multi-step workflows, software development teams face an unprecedented testing crisis. Unlike traditional software—where deterministic inputs yield predictable outputs—AI agents reason, select tools, observe results, and iterate over dozens of turns. Consequently, modifying a single system prompt, updating a tool description, or upgrading an underlying foundational model can drastically alter an agent’s behavior without leaving a clear trail of breadcrumbs. In many cases, engineering teams find themselves navigating a frustrating cycle of manual guesswork, deploying changes blindly, and discovering regressions only after updates reach end-users.
To combat this systemic volatility, the artificial intelligence engineering community has increasingly turned to systematic evaluations, commonly known as "evals." Much like automated test suites in traditional software engineering, an agent eval subjects an autonomous system to a predefined task, executes the workflow, and judges the outcome against objective criteria. However, because agents introduce layers of non-determinism and complex decision-making trees, designing robust evaluation frameworks requires an architectural paradigm shift. Industry researchers, machine learning practitioners, and enterprise platform architects are now establishing rigorous standards to transform agent development from a speculative art into a measurable, repeatable engineering discipline.
The Anatomy of Agentic Failure: Why Traditional Testing Falls Short
In single-turn interactions, evaluation is conceptually straightforward: one user prompt elicits one model response, which a validation script or human grader checks against an expected output. Autonomous agents fundamentally break this linear model. An agent must ingest a complex goal, break it down into actionable sub-steps, query external APIs or databases, interpret the returned data, and dynamically adjust its execution path. This multi-turn operational loop means that errors do not remain isolated; instead, they compound. A minor reasoning error or a misplaced API argument early in a sequence alters the state for every subsequent step, causing the agent to drift further off course.
To effectively diagnose these cascading failures, engineering teams must dissect agent behavior into three distinct, hierarchical layers: reasoning, action, and overall execution.
The first layer, reasoning, encompasses the agent’s ability to comprehend the overarching objective, decompose it into logical sub-tasks, and establish a correct sequence of operations. A classic failure at this layer occurs when a travel-booking agent attempts to execute a flight reservation before verifying seating availability.
The second layer involves action, which governs tool selection, argument formatting, and execution timing. Even if an agent possesses flawless reasoning, it may fail at this juncture by passing an unrecognized city code or invalid parameter to a backend API.
The final layer evaluates overall execution efficiency and task completion. An agent might successfully secure a flight reservation, but achieve this goal inefficiently by repeatedly polling the same database for information it had already retrieved during earlier turns.
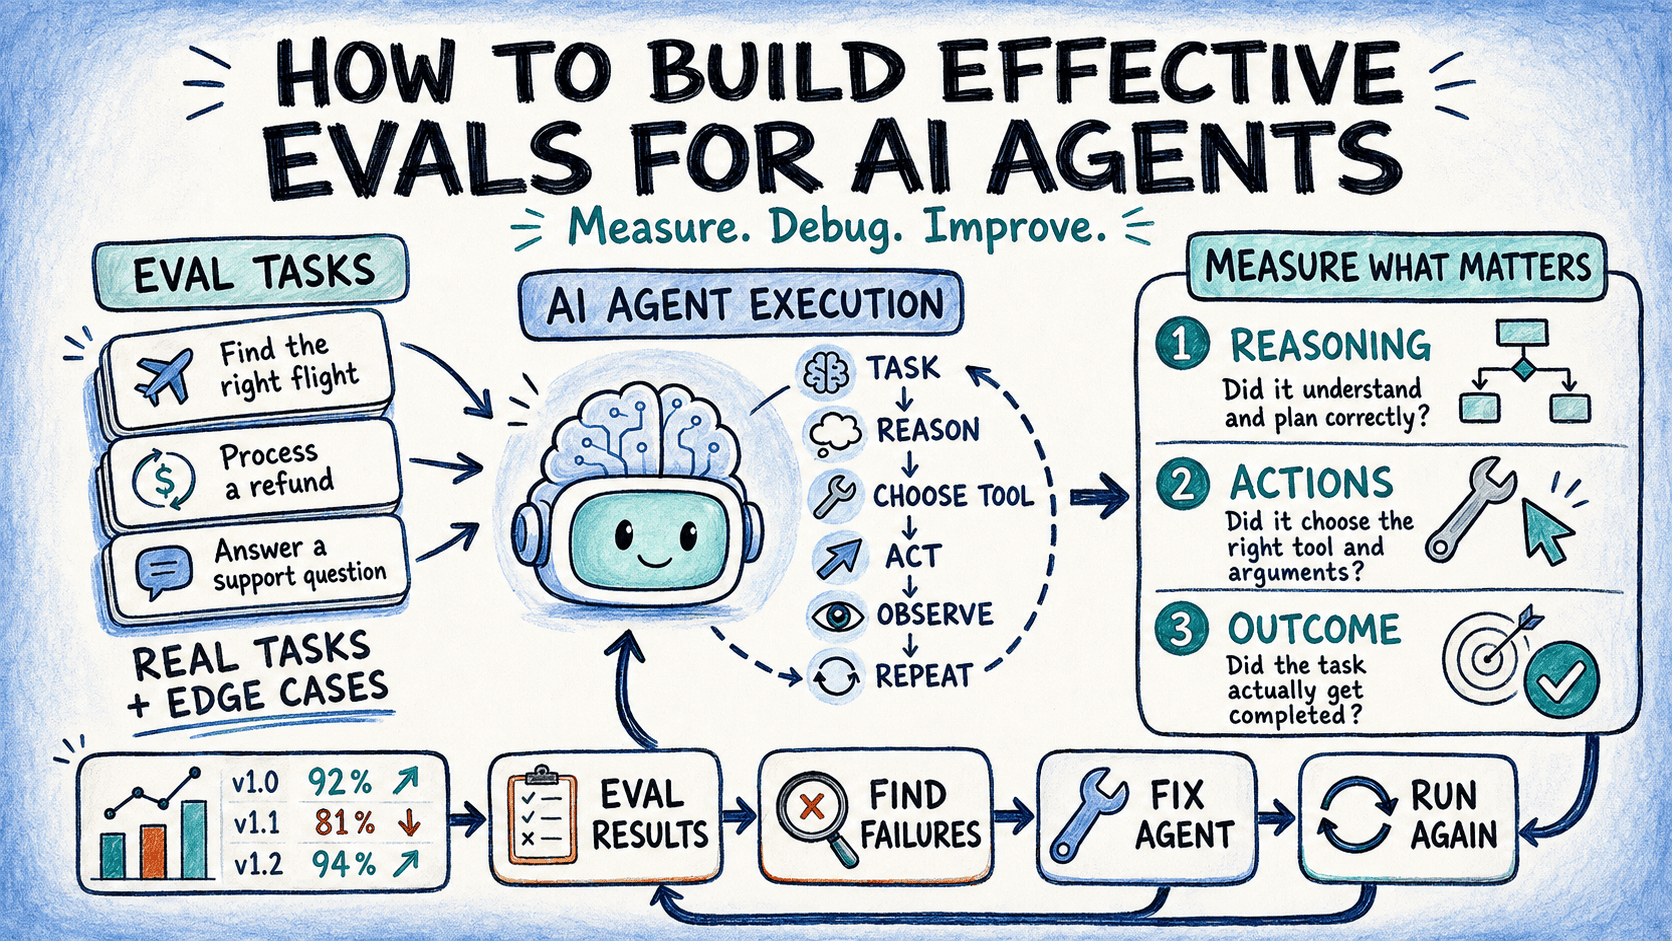
By categorizing failures across these structural layers rather than relying on a binary pass-fail score, developers can pinpoint the exact origin of a regression. Furthermore, frontier language models introduce an additional complication: autonomy. Because advanced models possess high degrees of flexibility, an agent may discover a completely valid, highly creative solution that human designers never anticipated when drafting the test case. Rigid evaluation graders that demand strict adherence to a predetermined sequence of steps will mistakenly flag these innovative solutions as failures. Consequently, modern evaluation frameworks are shifting toward outcome-based grading that assesses the reasonableness of the methodology rather than enforcing a monolithic path.
Sourcing Tasks and Constructing Initial Evaluation Suites
Building a comprehensive evaluation suite does not require an enterprise to launch hundreds of complex test cases on day one. Industry consensus suggests that engineering teams should start small, curating a handful of focused, high-impact tasks that target core business workflows, known edge cases, and scenarios that historically triggered regressions prior to software releases. Turning these manual pre-release checks into repeatable, automated tasks provides immediate utility and establishes a baseline before systems grow overwhelmingly complex.
A well-balanced evaluation suite must incorporate both positive and negative test cases. For instance, an evaluation set for a customer service assistant should feature queries that explicitly require external database lookups alongside queries that can be directly answered using internal context or general knowledge. This dual-testing approach ensures that the evaluation measures genuine decision-making capability rather than rewarding an agent that mindlessly executes the same tool for every incoming request.
When drafting these tasks, clarity and objectivity are paramount. Test specifications must contain unambiguous success criteria, ensuring that two independent reviewers examining the same execution transcript would arrive at the exact same conclusion regarding a pass or fail. If a test case relies on implicit assumptions or vague instructions, the resulting score will measure the ambiguity of the task design rather than the capability of the agent. Moreover, establishing a verified reference solution for each task acts as an invaluable sanity check. If a highly capable frontier model consistently fails a specific test case, developers can use the reference solution to determine whether the task itself is logically solvable or if the automated grader is malfunctioning.
Matching Graders to Evaluation Layers
Selecting the appropriate grading mechanism is critical to extracting actionable insights from an evaluation run. Not all aspects of agent behavior warrant the same evaluation methodology. Modern engineering practices typically categorize graders into four primary archetypes, each tailored to specific operational layers:
Deterministic graders—such as string matching, assert statements, and database checks—offer exceptional speed and cost efficiency for unambiguous outputs. However, they remain highly vulnerable to minor formatting variations and cannot recognize valid, alternative solutions outside their pre-programmed parameters.
Code-based graders employ custom test scripts, API validation checks, and state-validation assertions to evaluate functional behaviors, tool-call arguments, and complex state changes. While powerful, they demand reliable testing logic and a meticulously controlled, isolated test environment.
Model-based graders leverage large language models to score execution transcripts against detailed rubrics. These are particularly effective for evaluating subjective, open-ended, or freeform outputs, though they require continuous calibration against human judgment to prevent scoring drift.
Finally, human review remains the gold standard for high-stakes judgment calls that automated scripts or models cannot safely adjudicate alone, even though manual review is resource-intensive and difficult to scale across continuous deployment pipelines.
By aligning the grader type with the specific behavior being verified, teams can automate routine checks while reserving human expertise for nuanced edge cases. Crucially, default evaluation strategies should prioritize final outcomes over rigid step-by-step enforcement, reserving strict sequential checks exclusively for safety-critical workflows where specific procedural steps are legally or operationally mandatory.
Engineering the Test Harness and Managing Non-Determinism
An evaluation is only as trustworthy as the execution harness in which it runs. To ensure experimental validity, every trial must begin in a pristine, isolated state. Residual data files, cached API responses, or shared execution histories can easily skew performance metrics, creating a false impression of agent reliability.
Furthermore, binary scoring mechanisms frequently obscure critical performance nuances. Treating every complex task as a simple pass or fail hides partial progress. An agent that successfully diagnoses a customer issue and verifies account identity but ultimately fails to process a refund is vastly superior to an agent that fundamentally misunderstands the customer’s request. Implementing partial credit scoring systems provides granular visibility into incremental model improvements.
Because generative AI models inherently exhibit non-determinism—rarely producing identical execution paths across multiple runs—relying on a single trial is statistically misleading. Enterprise teams increasingly adopt specialized statistical metrics, such as pass@k and pass^k, to quantify reliability. The pass@k metric measures the probability of achieving at least one successful execution across $k$ attempts, making it ideal for exploratory tasks where finding a valid solution eventually is sufficient. Conversely, pass^k measures the strict probability that all $k$ attempts succeed consecutively, which is essential for customer-facing production agents where consistency and predictability are paramount.
Transcript Inspection and Continuous Development Integration
Dashboards and aggregate metrics provide high-level visibility, but they cannot replace qualitative transcript reviews. Reading through execution transcripts allows engineers to examine the internal reasoning chains, evaluate tool-call payloads, and inspect final system states. When an evaluation task fails, manual inspection reveals whether the agent genuinely malfunctioned or if the automated grader incorrectly rejected a valid, creative solution. This diagnostic step frequently exposes flawed grader logic or ambiguous test specifications. In numerous real-world engineering instances, resolving grading bugs alone has yielded dramatic performance gains on internal benchmarks without requiring any modifications to the underlying model.
As evaluation suites mature, engineering teams must guard against saturation. When an agent successfully passes 98% of a static test suite, the evaluation ceases to be a useful diagnostic tool for ongoing improvements. While such mature suites remain invaluable as regression guards to catch breaking changes before deployment, developers must continuously inject increasingly difficult, novel failure cases to challenge newer models.
Ultimately, the integration of automated evaluations transforms artificial intelligence development from an ad-hoc, trial-and-error exercise into a rigorous engineering lifecycle. By embedding evaluation suites directly into continuous integration pipelines—triggering automated test runs on every pull request and blocking code merges upon performance regression—organizations can systematically measure progress. When paired with live production monitoring, user feedback loops, and regular transcript audits, comprehensive evaluation frameworks establish a continuous operational cycle of testing, measuring, diagnosing, and improving, ensuring that autonomous AI agents remain reliable, predictable, and aligned with user needs.