Optimizing Small Language Models for Narrow Automation: Reusing the Prompt Prefix with a Key-Value Cache

The deployment of Small Language Models (SLMs) in production environments has increasingly shifted from broad, general-purpose conversational agents to highly specialized, narrow automation tasks. Organizations seeking to automate repetitive workflows—such as customer support ticket routing, document classification, and data extraction—frequently turn to lightweight architectures like the 0.5-parameter Qwen2.5-Instruct model. While these smaller models offer substantial cost and latency advantages over massive frontier models, engineering bottlenecks remain during high-volume inference. Addressing these inefficiencies requires moving beyond standard inference loops and adopting architectural optimizations designed to eliminate redundant computations.
Building upon previous methodologies that constrain output spaces to streamline classification accuracy, performance engineers are now turning their attention to prompt prefix optimization. In typical narrow automation pipelines, prompts remain remarkably static. A comprehensive task instruction, a detailed taxonomy definition, and a robust set of few-shot examples constitute the vast majority of the token count. Only a negligible suffix—representing the incoming data point, such as an individual support ticket—changes dynamically from one API call to the next.
Despite this overwhelming structural redundancy, standard transformer inference pipelines traditionally re-encode the entire prompt from scratch on every invocation. This architectural limitation results in substantial computational waste, particularly when running local models on commodity hardware or managing high-throughput enterprise pipelines. Recent benchmarking data highlights how implementing a key-value (KV) cache to store and reuse static prompt prefixes can slash overall inference times by more than half, turning lightweight SLMs into exceptionally viable solutions for industrial automation.
The Mechanics of Transformer Redundancy and KV Caching
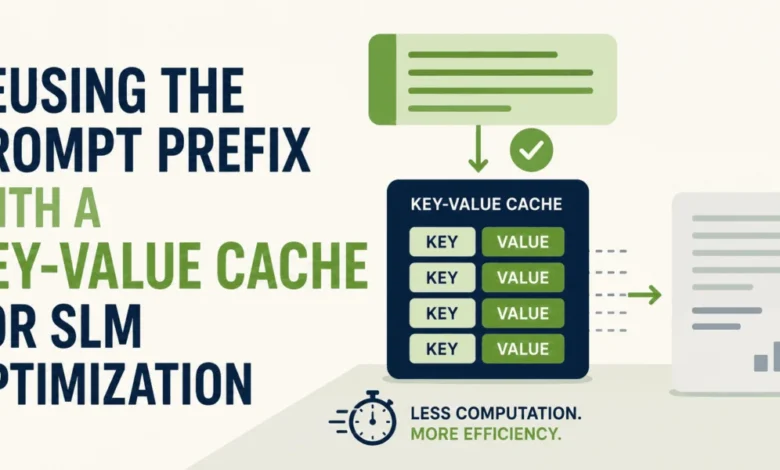
To understand the operational gains of prefix caching, it is necessary to examine how transformer models process sequential data. During the pre-fill phase of inference, transformers compute a key vector and a value vector for each token across every network layer. Crucially, the key and value vectors for any given token depend exclusively on the tokens positioned to its left.
Consequently, when an instruction block, system prompt, and example set remain identical across thousands of sequential requests, the resulting key-value vectors for that prefix are mathematically identical on every call. Recomputing these vectors repeatedly for every layer during every inference cycle introduces unnecessary computational overhead. By computing the prefix’s key-value tensors once, storing them in memory via a dynamic cache mechanism, and subsequently feeding the model only the newly altered suffix tokens, engineers can drastically reduce the computational burden of the pre-fill phase.
This strategy fundamentally transforms how hardware resources are utilized. Rather than processing a 167-token prompt for every single transaction in a 600-item batch, the system processes a 145-token static prefix exactly once. Subsequent inferences only evaluate the incremental 22-token difference, effectively shrinking the active pre-fill workload to a fraction of its original size.
Empirical Benchmarks and Performance Evaluation
To quantify the practical impact of prompt prefix reuse, controlled benchmarks were executed using the Qwen2.5-0.5B-Instruct model in float16 precision via the Hugging Face Transformers library. The tests were conducted on an Apple M2 MacBook Air equipped with 24GB of RAM and a 16-core Neural Engine, running a standardized classification workload consisting of 600 customer support tickets divided evenly across three categories: billing, technical, and account issues.
In the baseline configuration, the complete prompt—incorporating the static system instructions, taxonomy definitions, few-shot examples, and the dynamic ticket suffix—was re-encoded in full for every individual record. Utilizing constrained scoring to isolate the primary logits of distinct label tokens, the baseline loop required an average of approximately 308.1 milliseconds per ticket. Processing the entire 600-item dataset demanded a cumulative execution time of 184.85 seconds.
Conversely, implementing the prefix caching strategy yielded a dramatic improvement in throughput. By populating a dynamic cache with the static instruction block prior to the inference loop, and subsequently executing classification tasks by referencing the cached key-value pairs, the average processing time dropped to 133.5 milliseconds per ticket. Total execution time for the identical 600-item workload fell to 80.07 seconds.
This represents an overall runtime reduction of approximately 57 percent. Crucially, these performance gains were achieved without altering the model’s outputs or sacrificing classification accuracy. Verification checks confirmed that the cached execution path produced identical predictions to the uncached baseline across every distinct record, proving that prefix caching functions as a pure computational optimization rather than an approximation technique.
Scalability and Architecture Implications for Enterprise Deployment
The economic and operational implications of these findings extend far beyond local development benchmarks. As enterprise AI architectures scale to handle millions of daily automated transactions, infrastructure costs are heavily dictated by token processing efficiency and hardware utilization.
The performance gains delivered by prefix caching scale directly with the ratio between static and dynamic content within a given prompt framework. In operational contexts where robust system instructions, complex few-shot examples, and strict formatting guidelines occupy hundreds of tokens—while the incoming data payload remains brief—prefix caching transforms what would otherwise be an inefficient pipeline into a highly responsive automation engine. Ironically, under this optimization paradigm, highly detailed, comprehensive instructions are rewarded with greater efficiency, counterbalancing the traditional intuition that verbose prompts invariably degrade system performance.
Industry analysts note that adopting architectural strategies of this nature bridges the gap between theoretical model capabilities and practical production requirements. While large language models frequently dominate industry headlines, small language models paired with advanced caching and constrained decoding mechanisms offer a compelling alternative for organizations prioritizing data privacy, predictable latency, and minimal operational expenditure.
Broader Industry Trends in SLM Optimization
The successful implementation of key-value cache reuse for small language models mirrors a broader industry movement toward inference-time efficiency. As the artificial intelligence sector matures, engineering focus has largely pivoted away from simply scaling parameter counts upward, toward optimizing how existing models execute within resource-constrained environments.
Techniques such as quantization, speculative decoding, structural pruning, and prefix caching collectively represent a maturing engineering discipline focused on hardware-software co-design. For developers building narrow automation pipelines, these methodologies eliminate the historical compromise between model intelligence and operational speed.
By treating the prompt infrastructure as a persistent state rather than a series of isolated, stateless events, systems architects can unlock the full potential of lightweight models. As these optimization patterns become standardized within major machine learning frameworks, the deployment of specialized SLMs for high-throughput enterprise automation will likely accelerate, establishing a new baseline for cost-effective artificial intelligence integration.